

Quick Summary: A cache invalidation bug is a production failure where the cache and the source of truth disagree, and the application trusts the cache. AI debuggers miss three patterns – the stale-after-write race, the split-brain cache, and the orphan invalidation – because each requires reasoning about distributed state.
The Cache That Couldn’t Be Wrong (But Was)
Cache invalidation bugs rarely look like cache bugs. If your production data is intermittently wrong – inventory counts off a few times an hour, a record that reads “active” in one service and “discontinued” in another, bugs that vanish for a moment after every deploy – the problem is almost certainly a cache invalidation bug, not the null pointer your AI debugger keeps flagging. Those were the exact symptoms our team at ScriptsHub Technologies walked into last quarter, when an e-commerce client called us mid-incident. Nothing was crashing – just silently wrong inventory counts, three to five times per hour, with orders shipping the wrong number.
The on-call developer had spent two days on it. He ran the stack traces through GitHub Copilot and Claude. Both AI debuggers gave the same answer: a NullPointerException on line 247, fix with a null check, ship. He almost did.
The bug was three services away. The team was running Redis fronted by a Kafka invalidation channel, and the Kafka broker had silently run out of disk space, dropping cache invalidation events for 48 hours. The cache was serving stale “active” status for discontinued products. The null was a symptom four hops downstream from the disease.
That’s the trap – the symptom never points at the cache. They surface as null pointers, off-by-one errors, flaky tests. AI debuggers see each one in isolation and confidently suggest a fix that masks the disease.
What a Cache Invalidation Bug Actually Is
A cache invalidation bug – famously one of the two hardest things in computer science -is a production failure where the cache and the source of truth disagree, and the application trusts the cache. It rarely lives in caching logic – it lives in the gap between a write and the invalidation that should follow.
Most cache invalidation bugs come from a write nobody connected to the invalidation logic – a new endpoint, an admin tool, a background job updating the database without telling the cache. AI debuggers miss these because the failure crosses service, timing, and infrastructure boundaries at once. AWS documents the same family of failure modes in their guide to caching challenges and strategies at scale.
How to Know It’s a Cache Bug Before You Start Debugging
Three questions, in order, before reaching for stack traces:
1. Is the bug shape consistent with a cache? Cache bugs are intermittent, correlate with traffic patterns, and disappear briefly when a deploy clears the cache. Suspect the cache before the code.
2. Where is the write that should have invalidated it? Every cache bug has a corresponding write somewhere. If you cannot find a write path that would have triggered invalidation, that absence is the bug.
3. Did the invalidation actually run? Logs, not assumptions. If you don’t have invalidation telemetry, you are guessing.
If a bug clears all three checks, you’re looking at one of the patterns below.
Why AI Debuggers Miss Cache Invalidation Bugs
AI debuggers fail on cache invalidation for three structural reasons.
1. They analyse code within a single service boundary. A cache invalidation bug crosses boundaries – write in service A, cache in service B, read in service C. Static analysis on any one finds nothing wrong.
2. They cannot reason about temporal behaviour. Cache bugs depend on ordering – a read between a write and the invalidation it triggered. AI debuggers pattern-match on code, not event timing.
3. They treat infrastructure as invisible. When a broker runs out of disk, when Redis fails over, when a CDN edge returns a stale value, the AI debugger has no visibility. It analyses the code, finds it correct, and stops.
We documented this gap in our blog on AI debugging tools masking production root causes.
Cache invalidation bugs are observability bugs in disguise. The fix is rarely a code change – it is making the cache’s behaviour visible enough that a bug cannot hide.
The 3 Cache Invalidation Bug Patterns AI Debuggers Always Miss
Pattern 1: The Stale-After-Write Race
The most common cache invalidation bug. A user updates a record, the cache is invalidated, but a concurrent read populates the cache with the old value from a read replica that hasn’t caught up. The cache is poisoned, and only TTL expiry fixes it.

The fix. Move cache population behind the write path (write-through caching), or version the cache keys so a stale-after-write population is replaced when the next invalidation fires.
Pattern 2: The Split-Brain Cache
Two services read the same record but cache it independently. They invalidate independently and go stale at different times. For minutes – sometimes hours – they see different data for the same record.
In our incident, Inventory and Fulfilment both cached product status. One was getting “discontinued” from the database; the other was still seeing “active” from its cache. Every order touching a recently-discontinued product produced inconsistent results.
How AI debuggers see it. Each service looks correct in isolation. AI debuggers suggest “add logging” or “ensure consistency” without saying how.
How to find it. Search for the same database query or ORM call across multiple services.
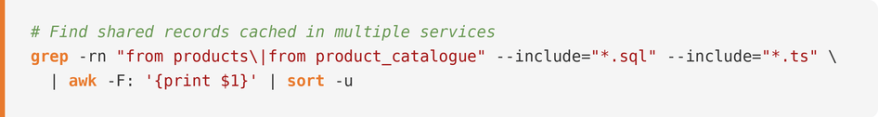
The fix. Centralise the read path. Introduce a Product Service as the single source of cache truth, or front all services with a shared Redis namespace and a standard invalidation channel so every consumer invalidates the same key the same way.
Pattern 3: The Orphan Invalidation
The pattern from our incident – and the hardest to catch. The application emits an invalidation event, but the event bus drops it – broker out of disk, Kafka partition failover, Redis pub/sub miss. The cache never hears about the write and serves stale data until TTL expires, or indefinitely if no TTL.

How AI debuggers see it. Application code: correct. Cache code: correct. The broker is invisible. Most teams instrument the publisher and the cache, but not the broker – so a broker failure between them produces no error anywhere.
How to find it. This is where observability earns its keep. Three independent signals:
- Write-side: invalidation events published per minute
- Broker-side: events delivered per minute
- Cache-side: invalidations applied per minute
If those numbers disagree, you have an orphan invalidation. We have never seen this bug found without those metrics.
The fix. Fix the broker – almost always operational (disk, memory, partitioning). Then add a reconciliation job that replays missed invalidations from a durable log, so the next broker incident is a brief degradation rather than multi-day corruption.
A Comparison: The 3 Cache Invalidation Patterns Side by Side

Inside the Incident: What Four Days of Diagnosis Surfaced
The engagement produced clear numbers:
- 3 of 3 patterns were present (stale-after-write in checkout, split-brain in product status, orphan invalidation in catalog updates)
- 48 hours of stale product data corrupting fulfilment before we were engaged
- 0 alerts fired before the incident
- 4 days from engagement to root cause, with the orphan invalidation hardest to find
- Time-to-detection dropped from ~48 hours to single-digit minutes once the publish-vs-deliver gap alert fired
The fix was not in the application code. The fix was in the observability around the cache.
What Good Cache Observability Looks Like
Three metrics catch most cache invalidation bugs in production:
Publish rate. How many invalidation events did the application emit?
Delivery rate. How many events did subscribers receive?
Apply rate. How many invalidations updated the cache?
When all three match, your cache is honest. When they diverge, you have a bug – usually before users notice. The broader observability discipline is in our vibe-coded hardening playbook.
When to Just Remove the Cache
Sometimes the right answer is to delete the cache. If data changes more often than the TTL, or if the database can handle the read load, the cache is costing you incidents for no benefit. For data that changes more than once a minute, removing the cache is usually the right call.
The Bottom Line: AI Sees Code, Engineers See Systems
AI debuggers will keep getting better. Their context windows will grow, they will eventually trace across boundaries, some will model temporal behaviour. None of that is true today. Every cache invalidation bug we have diagnosed required a human reasoning about distributed state and infrastructure failure modes.
If your team ships AI-suggested fixes without checking the broker, the replicas, or the write paths, you are accumulating technical debt that compounds silently. The next incident will be longer than the last.
Struggling with a cache bug your AI debugger can’t find? info@scriptshub.net or www.scriptshub.net.
Frequently Asked Questions
Q. What is a cache invalidation bug?
A cache invalidation bug is a production failure where the cache and the source of truth disagree, and the application trusts the cache. It lives in the gap between a write and the invalidation that should follow.
Q. Why can’t AI debuggers find cache invalidation bugs?
AI debuggers analyse code within a single service boundary, cannot reason about temporal event ordering, and treat infrastructure failures as invisible. Cache bugs cross all three limits.
Q. What is the stale-after-write race?
The stale-after-write race happens when a concurrent reader populates the cache with the old value after invalidation has fired, because the read hits a database replica that has not yet caught up. The cache is poisoned until TTL expires.
Q. What is a split-brain cache?
A split-brain cache is when two or more services independently cache the same record and invalidate on different schedules. They see different values for the same record until the caches realign.
Q. What is an orphan invalidation?
An orphan invalidation happens when the application publishes an invalidation event, but the event bus silently drops it before the cache hears about it. The cache serves stale data until TTL expires – or indefinitely if no TTL is set.
Q. How do you detect a cache invalidation bug in production?
Three metrics catch most cache invalidation bugs: events published, delivered, and applied per minute. When those numbers diverge, a bug exists. Without those metrics, cache bugs are nearly invisible.
Q. Should you always cache distributed data?
No. If data changes more often than the TTL, multiple services need fresh reads, or the database can handle the load, removing the cache is often cheaper than maintaining invalidation correctness.


